• Senior Data Engineer
  • Berlin, Germany
  • Available immediately

  • 20 TB a day.
  • 99.9% availability.
  • Zero downtime.

Google Cloud Certified Professional Data Engineer with 7+ years of streaming, CDC and batch pipelines across telecom, banking and energy.

02IngestAbout

I build data platforms that stay correct at scale. As technical owner and architect of the Vodafone Digital Data Store, I kept 20 TB a day flowing at 99.9% availability, with validation, alarms and monitoring built into the pipeline itself.

My work sits where streaming meets modeling: Oracle GoldenGate CDC into Apache Kafka, Spark Structured Streaming with checkpointing, restart and replay, and analytics-ready models served through Apache Impala.

I led a team of three engineers, set our engineering standards and mentored two junior colleagues to mid-level. I work spec-first with AI assistance, and every output is reviewed and validated before it merges.

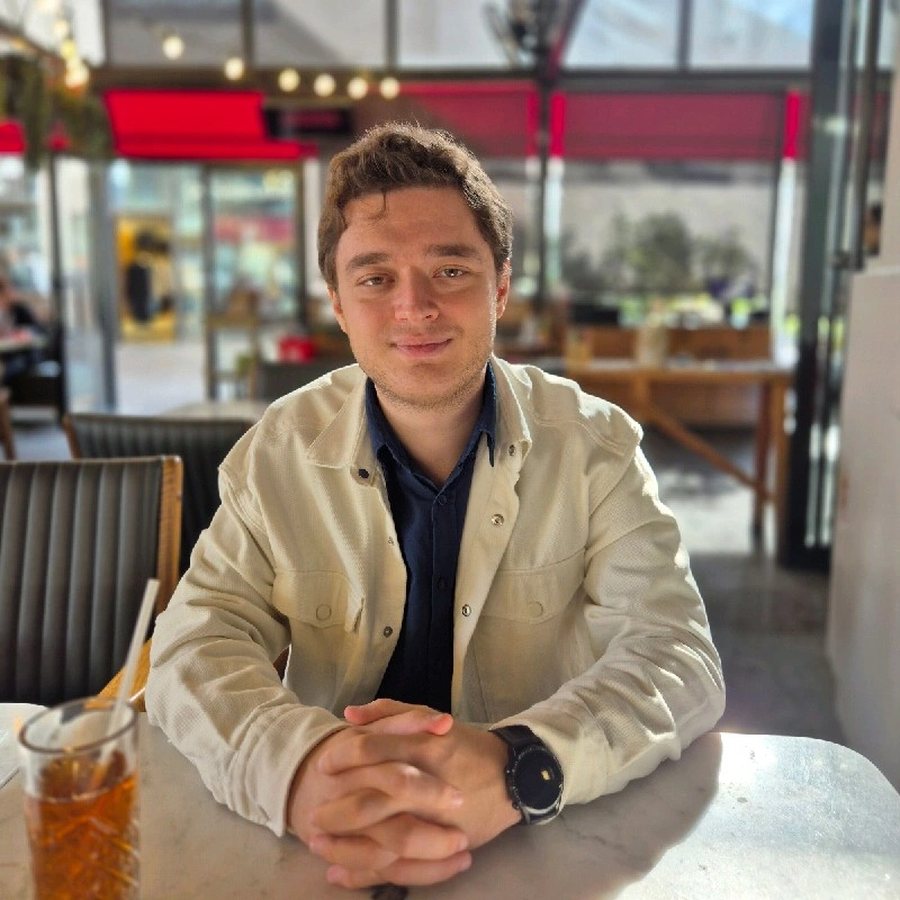
Portrait of Yunus Alper Körükcü
Y.A. KörükcüBerlin
Location
Berlin, Germany
Experience
7+ years
Work permit
EU Blue Card, no sponsorship needed
Availability
Immediately
Languages
English (fluent), Turkish (native), German (A1, learning)
Education
BSc Computer Engineering, Karabük University
03TransformSelected work

Case file 01 · Bentego, client Vodafone · 2022–2026

VodafoneDigital DataStore

I was the technical owner and architect of the platform: 20 TB of daily data at 99.9% availability. I led its modernization with zero downtime, validated by running old and new versions side by side on real traffic.

Pipeline stage Scroll to advance
VALIDATION · ALARMS · MONITORING · DATA QUALITY 01OracleSOURCE 02GoldenGateCDC 03KafkaEVENT BUS 04SparkSTRUCTURED STREAMING 05KafkaTOPICS 06HBase · HiveROW KEYS · PARTITIONS 07ImpalaSERVE 08SupersetDASHBOARDS 09AirflowSCHEDULING · MONITORING UI
  1. 01

    Oracle sources

    Operational data starts in Oracle source systems.

  2. 02

    GoldenGate CDC

    Oracle GoldenGate captures each change and streams it into Kafka.

  3. 03

    Apache Kafka

    Kafka carries the change stream, with producer settings tuned on the write path.

  4. 04

    Spark Structured Streaming

    Streaming transformations with checkpointing, restart and replay for failure recovery.

  5. 05

    Kafka topics

    Processed events land in Kafka topics on the way to the serving layer.

  6. 06

    HBase and Hive

    HBase row keys and Hive partitioning designed for query performance.

  7. 07

    Apache Impala

    Analytics-ready models served through Impala, partitioned for fast reads.

  8. 08

    Apache Superset

    Reporting dashboards for five stakeholders.

  9. 09

    Airflow and data quality

    Streaming jobs scheduled on Airflow for one monitoring UI, with alarm, monitoring and data quality ETLs across the flow.

  10. 10

    The outcome

    10× throughput and 40% lower latency on the critical pipeline, delivered with zero downtime.

  • 10×

    Throughput on the critical DDS pipeline after the modernization

  • 40%

    Lower latency on the same pipeline

  • 20TB

    Of data processed every day

  • 99.9%

    Availability, with validation and alarms built in

6015

Spark jobs consolidated

25%

Of a 99-node cluster’s resources freed

0s

Downtime. Old and new versions ran side by side on real traffic before the switch.

Team 3

Led three engineers and mentored two junior colleagues to mid-level.

Apache Kafka/Spark Structured Streaming/Airflow/BigQuery/GoldenGate/Apache Kafka/Spark Structured Streaming/Airflow/BigQuery/GoldenGate/
Impala/Hive/HBase/PostgreSQL/Python/SQL/Superset/Impala/Hive/HBase/PostgreSQL/Python/SQL/Superset/
04Lineage2019–2026

Experience

Seven years across energy, banking and telecom. Scroll to fly through them in order.

11/2019 – 05/2021 · Energy

Software Developer

CK Enerji

  • Built Apache Kafka based real-time pipelines for billing and smart meter data from millions of endpoints, where data correctness directly affected customers.
  • Developed backend services and REST APIs in Java and C# (.NET Core), deployed with Docker.
  • Kafka
  • Java
  • C# / .NET Core
  • PostgreSQL
  • MS SQL
  • Docker

05/2021 – 07/2022 · Banking

Big Data Engineer

Bentego · Client: Garanti BBVA Teknoloji

  • Built production data pipelines and dimensional models for credit risk and financial analytics at one of Turkey’s largest banks, working with analysts, risk and finance stakeholders.
  • Kept data quality, consistency and security under banking-grade regulatory compliance, with validation and lineage documentation.
  • SQL
  • Oracle Data Integrator
  • Apache Spark
  • Hadoop
  • PostgreSQL
  • Python

07/2022 – 08/2026 · Telecom

Senior Big Data Engineer

Bentego · Client: Vodafone · Berlin

  • Technical owner and architect of the Vodafone Digital Data Store: 20 TB a day at 99.9% availability.
  • Led a zero-downtime platform modernization: 10× throughput and 40% lower latency on the critical pipeline.
  • Consolidated 60 Spark jobs into 15 and freed 25% of a 99-node cluster’s resources.
  • Led a team of three engineers, set engineering standards and mentored two junior colleagues to mid-level.
  • Kafka
  • Spark Structured Streaming
  • GoldenGate
  • Impala
  • Hive
  • HBase
  • Airflow
  • Superset
05SchemaTools I use in production

Stack

01 · streaming

Streaming & Pipelines

  • Apache Kafka
  • Spark Structured Streaming
  • Apache Spark
  • Oracle GoldenGate CDC
  • Checkpointing, restart, replay

02 · modeling

SQL & Data Modeling

  • SQL
  • Performance tuning
  • Relational modeling
  • Dimensional modeling
  • Analytics-ready models
  • Tested SQL transformations

03 · storage

Databases & Warehouses

  • BigQuery
  • PostgreSQL
  • Oracle
  • MySQL
  • MS SQL
  • Apache Impala
  • Apache Hive
  • HBase

04 · quality

Data Quality

  • Validation in pipelines
  • Alarm and monitoring ETLs
  • Lineage documentation

05 · delivery

Orchestration & Delivery

  • Apache Airflow
  • Docker
  • Git
  • CI/CD
  • GitHub, GitLab, Bitbucket
  • Linux

06 · languages

Languages

  • Python
  • PyTest
  • SQL
  • Java
  • C#

07 · cloud

Cloud & Reporting

  • Google Cloud Platform
  • BigQuery
  • Apache Superset
  • JIRA

08 · ai

AI-Assisted Engineering

  • Spec-driven development
  • Agentic work with Claude
  • Review before merge
Grouped by pipeline layer
08OfflineBeyond the data

Off the clock

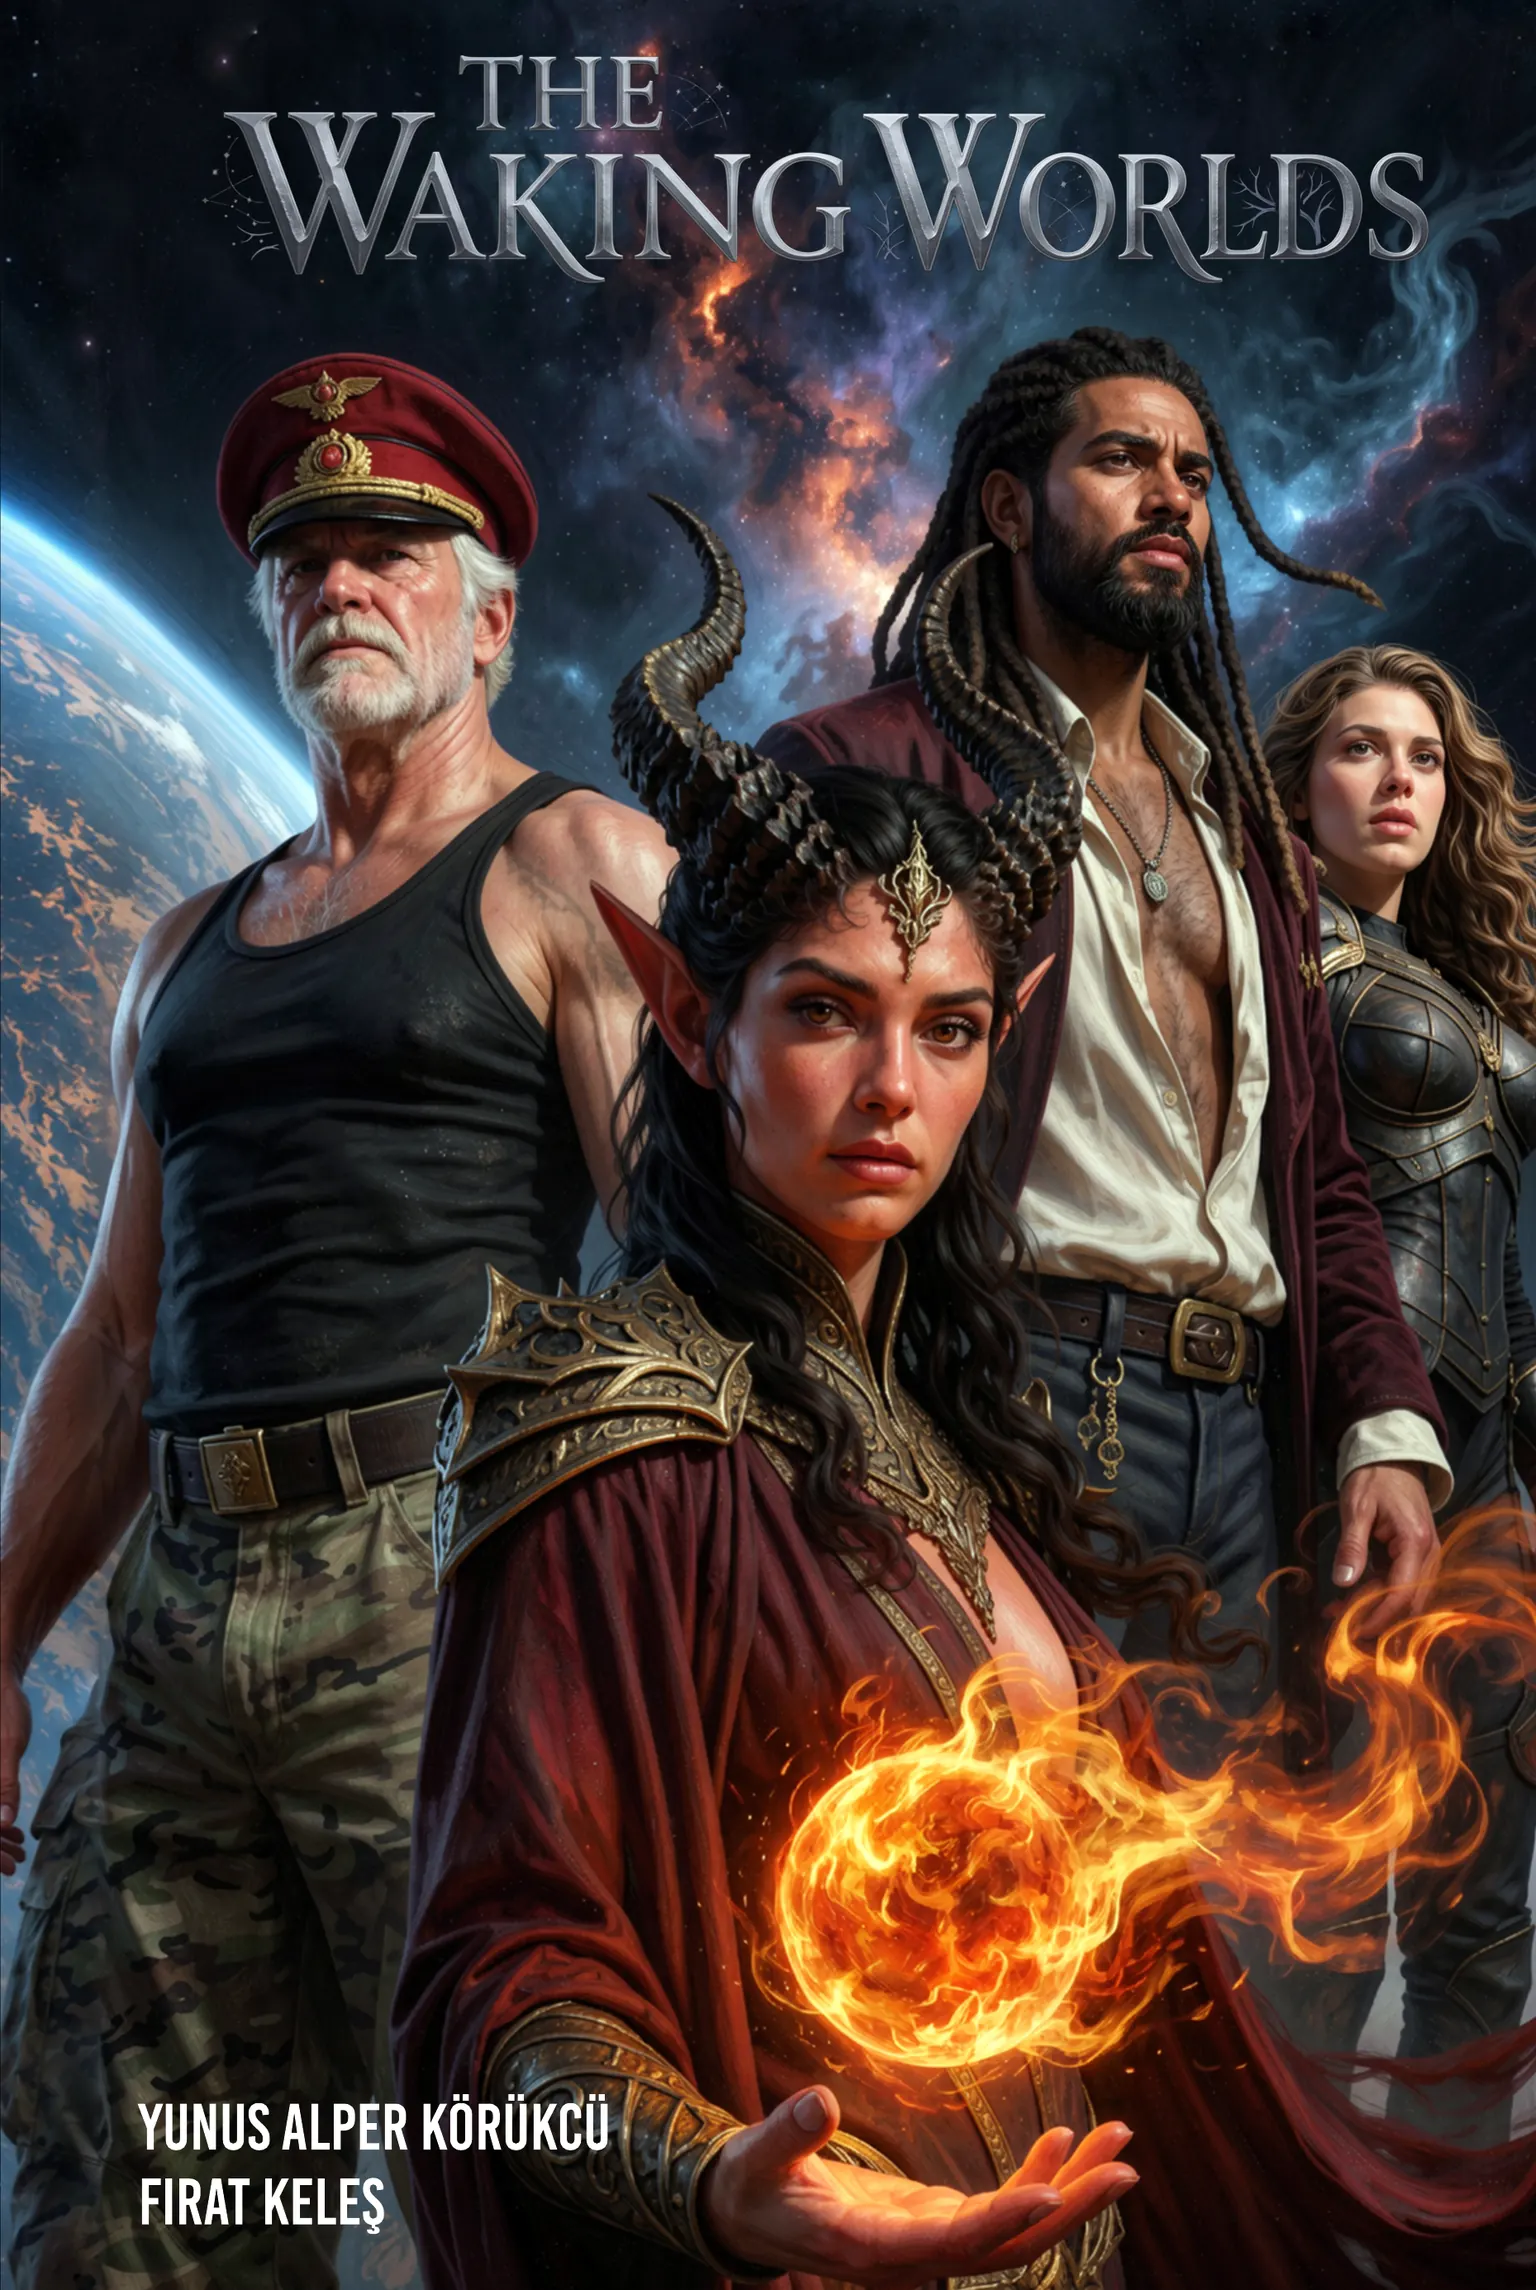
Outside of work, I write. I am the co-creator and co-author of The Waking Worlds, a science fiction and fantasy series that began as a years-long Dungeons & Dragons style roleplay with my friend Fırat Keleş.

Cover of The Waking Worlds, Episode One. Four characters stand in front of a nebula and a planet, and one of them holds a ball of fire.

Episode One · Out now

Yunus Alper Körükcü & Fırat Keleş

From the ashes we will rise.

For years, my friend Fırat Keleş and I ran a Discord server with exactly two members: us.

It started as a roleplay in Turkish, Dungeons & Dragons style. Fırat played every character who walked through the door. I played one.

A normal session ran two hours. The ones that got away from us ran six.

When the last season ended, I said we should write it down.

He agreed before I finished the sentence.

Turning years of Turkish chat logs into an English novel was a long job.

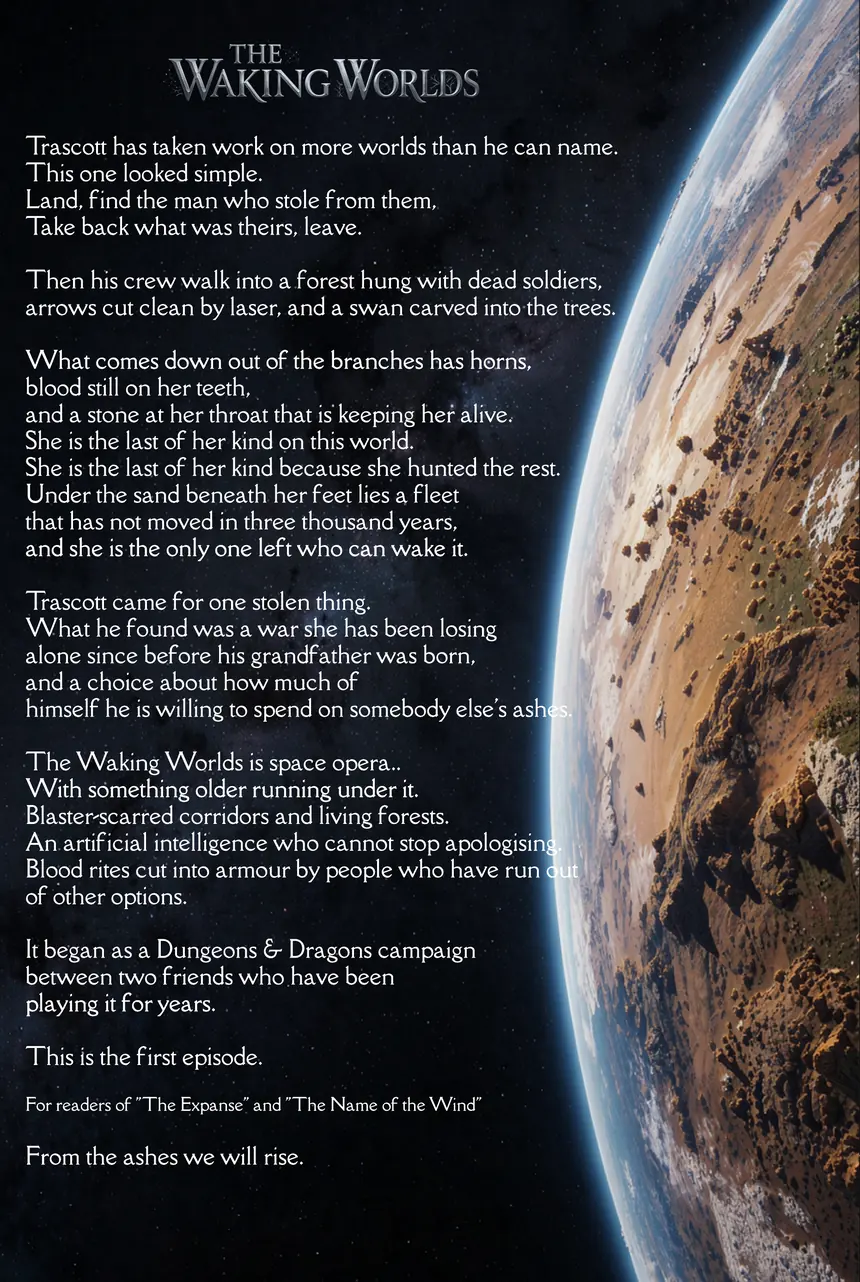
From the back cover

  1. Trascott has taken work on more worlds than he can name. This one looked simple.
  2. What comes down out of the branches has horns, blood still on her teeth, and a stone at her throat that is keeping her alive.
  3. Under the sand beneath her feet lies a fleet that has not moved in three thousand years, and she is the only one left who can wake it.
  4. The Waking Worlds is space opera. With something older running under it.
  • 80 colour illustrations
  • First book of a series
  • For readers of The Expanse and The Name of the Wind

Also off the clock

09SinkContact

Open to Senior Data Engineer and Data Platform Engineer roles.

  • Berlin, Germany
  • EU Blue Card holder
  • Available immediately
  • No visa sponsorship required